A prompt revision can improve one example while making another worse. If you judge it only by the latest response, that trade-off is easy to miss. A small evaluation set gives you a repeatable way to compare versions and a record of why you chose one. Five well-chosen cases can reveal more than a folder full of impressive screenshots.
Choose a real output to evaluate Suppose the task is drafting customer updates from approved project notes. The result must preserve dates, avoid invented commitments and fit the intended audience. Those requirements become the criteria. “Sounds intelligent” does not help a reviewer decide whether a wrong release date is acceptable.
Keep the criteria observable. You can check whether a date matches the source, whether an unknown remains unknown and whether the requested format is present. Style can be a criterion too, but it should not hide a failure in the facts.
Build a varied set Use one ordinary case, one with missing information, one with conflicting versions, one with an important exception and one that should trigger a request for more input. Fictional material works well when you want to avoid using customer data in an experiment.
Write the expected behaviour beside each case. For the missing-date case, the answer should not invent a date. For the conflicting-version case, it should report the conflict or follow an explicitly supplied authority rule. These notes make the review less dependent on memory.
Keep the comparison fair Run both prompt versions against the same inputs and output requirements. Record the tool and relevant settings. Do not quietly give the newer version a better source pack or a more generous length allowance, then attribute the improvement entirely to the prompt.
When possible, review the outputs without looking at the version label first. This does not remove every bias, but it makes it harder to reward the version you spent the most time writing merely because it is yours.
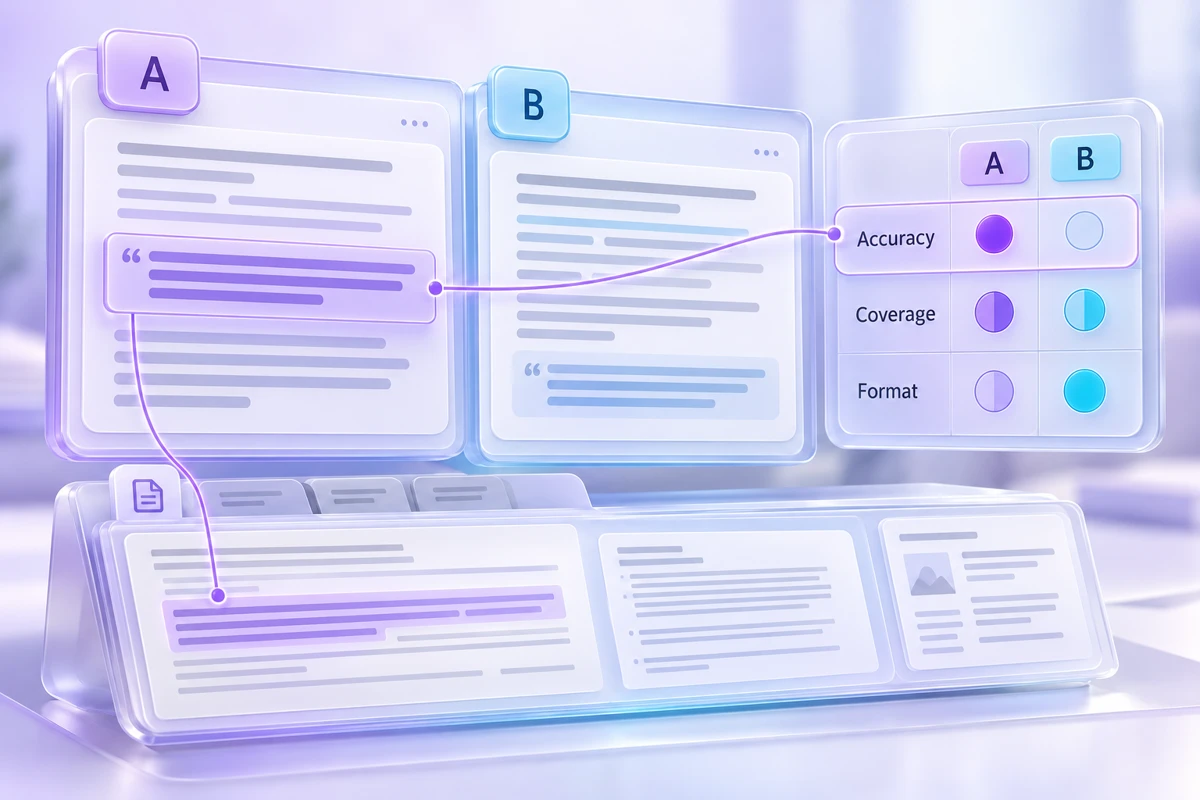
Record evidence for the score If a response fails a criterion, note the sentence or field responsible. “Wrong date: 12 June instead of 21 June” is actionable. A score of two out of five without an explanation is much harder to use when revising the prompt.
Weighted totals can help compare results, but keep critical failures visible. A response that invents a commitment should not win simply because its tone and formatting earned enough points elsewhere. Define any must-pass criteria before reviewing the outputs.
Make a decision you can revisit Accept the revision, keep the previous version or change one specific instruction and test again. Avoid rewriting everything after every disappointing result; you will lose the ability to identify which change mattered. Add a new test case when a real failure reveals a gap in the set.
Save the inputs, expected behaviour, outputs, evidence and decision together. The set is not a universal benchmark of the model. It is a working check for your task. Its value grows when it reflects the mistakes your workflow actually encounters and remains small enough that someone will keep using it.
Keep the inputs and review notes together in the Response Compare Pad, then save a backup you can reopen.